A prompt set written for your category
Give us your brand name, a short description, and up to three competitor names.
Waitlist open
For brand managers and SEO leads at mid-market companies, Seenby tracks how AI search engines mention, rank and describe your brand next to named competitors every week, so you have an answer the next time your CMO asks.
A look inside
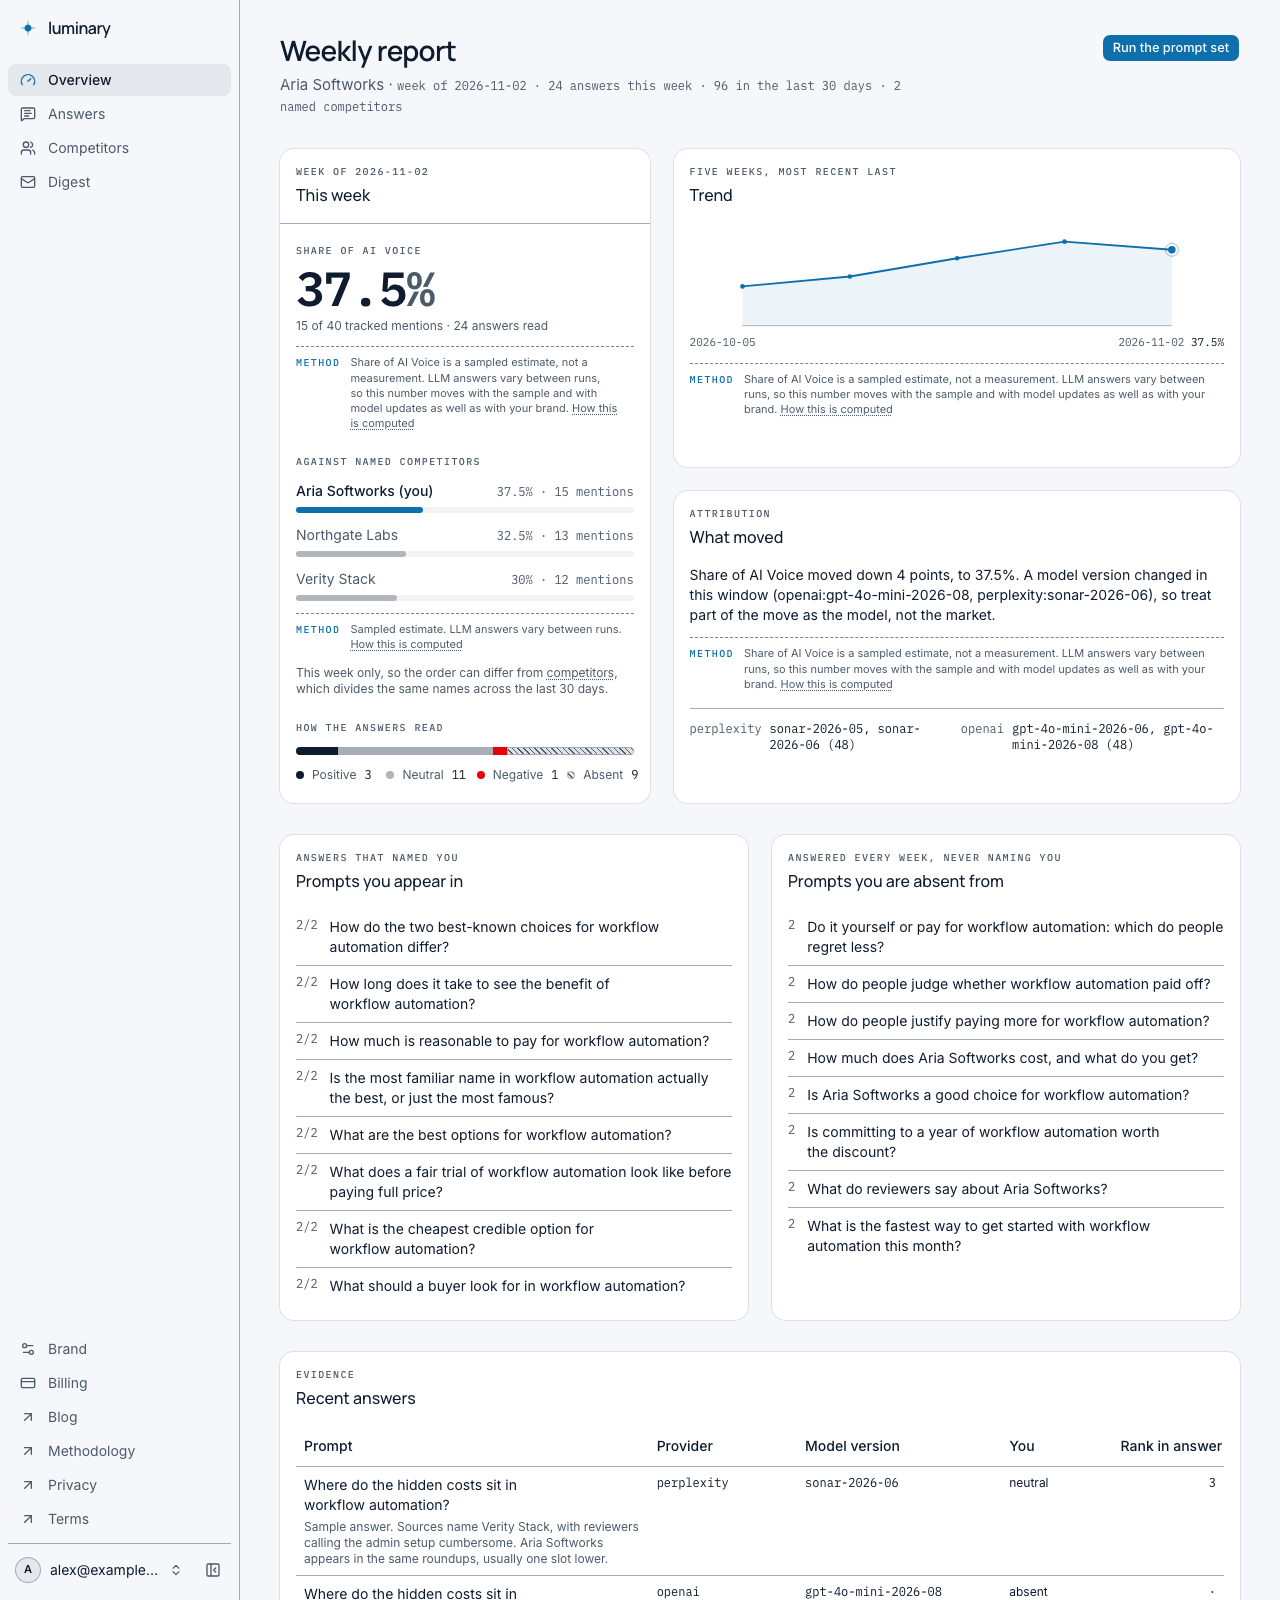
The problem
Today the options are manual spot-checking or an agency research project. Both give you one reading on one day from one prompt, which tells you almost nothing about whether you are gaining or losing ground. Crawl-based SEO tools cannot follow the question, because a generated answer is not a page in an index. Seenby is built to close that gap: the same prompt set, run on a schedule, parsed the same way each week, so a change in the number means something you can act on. When a change is more likely a model update than a market shift, we tag it as such rather than let you present it as a win.
What it will do
For what it covers, see the pages this site publishes.
Give us your brand name, a short description, and up to three competitor names.
Every response is parsed for brand and competitor mentions, classified positive, neutral, negative or absent, and given a ranking position within the answer. Consistent parsing is what makes week-over-week comparison worth reading.
A single headline metric your CMO can hold in their head, computed per brand per week and stored with its methodology caveat text attached to the record itself, so the number and its limits never travel separately.
Trend lines for Share of AI Voice, the sentiment breakdown behind them, the prompts where you are named and the prompts where you are not, and a benchmarking view against the competitors you entered.
Every stored response carries the model version that produced it, so a shift after a provider update can be told apart from a shift in how your market actually talks about you.
How it will work
Enter your brand name, a short description, and up to three competitor names. Seenby turns that into 50 to 100 category prompt templates, with a curated fallback set if generation comes up short, and shows you the list before anything runs.
The scheduled query engine sends the prompt set to OpenAI and Perplexity through a provider adapter, isolating per-prompt failures and continuing on the remaining provider if one is unavailable.
A PII-scrubbing step runs in the storage pipeline before any response becomes queryable, and every stored response carries a scrubbed flag and the model version that produced it. Then mentions, sentiment and ranking position are extracted.
Share of AI Voice is computed once per brand per week and stored together with the methodology caveat text, so every place the number appears can show what it does and does not support.
The weekly email brings top insights and drift alerts. The dashboard holds the 30-day trend, the sentiment breakdown, the competitor comparison, and the prompts where nobody named you.
Who it is for
For who it covers, see the pages under Who it is for.
Heads of SEO
You already track rankings and backlinks. Seenby is built to sit beside that work and report where generated answers name you, where they name a competitor instead, and which prompts never mention anyone in your set.
Content and comms leads
The dashboard lists the prompts where your brand is absent from the answer, which is a briefing document for the next quarter of content rather than a vanity chart.
Agency principals
Built for agency teams who need a repeatable weekly reading per client brand and a forwardable digest, with the methodology disclosure travelling alongside every score you pass on.
Questions
Two at launch: OpenAI and Perplexity. They sit behind a provider adapter interface so a cycle degrades gracefully if one is disabled. Gemini and Claude are not included in the current scope.
It is a repeated measurement of a non-deterministic system. The same prompt can return different answers on different days, and provider model updates can move a score without anything changing in your market. Seenby stores the model version behind every response and tags drift where it applies, and the methodology caveat is attached to every computed score rather than kept in a footnote.
Weekly. The query cycle runs your prompt set, the parser scores the responses, and the digest summarises the week. Real-time alerting outside the weekly cycle is not in scope.
Onboarding generates 50 to 100 prompt templates from your brand name, description and competitor names, with a curated fallback template set if generation fails or returns too few. A custom prompt builder is not part of the current scope.
A PII-scrubbing step runs in the response-storage pipeline before any response is queryable, and every stored response carries a scrubbed flag. The privacy page documents the basis for processing generated content that references real people.
No. Seenby measures and reports. What moves a generated answer is outside any tool's control, and we will not claim otherwise. The value is knowing your position, your competitors' positions, and which prompts leave you out.
Yes. You name up to three competitors during onboarding, and the parser extracts their mentions from the same responses as yours, which is what makes the comparison a like-for-like reading rather than two separate studies.
An email address. We will write when access opens, with what is included and what it costs, and nothing in between beyond occasional notes on the category.
Leave an email and we will write when access opens, with the surfaces covered, the caveats that come with the score, and the price. No sequence, no drip.
One email when it launches, and one now to confirm your address. Unsubscribe any time. Privacy.