A prompt set written for your category
Give us your brand name, a short description, and up to three competitor names.
What it will do
Seenby is not open yet, so this is what it is being built to do. Nothing a card names is a promise: the pages this site publishes are what it covers today.
Give us your brand name, a short description, and up to three competitor names.
Every response is parsed for brand and competitor mentions, classified positive, neutral, negative or absent, and given a ranking position within the answer. Consistent parsing is what makes week-over-week comparison worth reading.
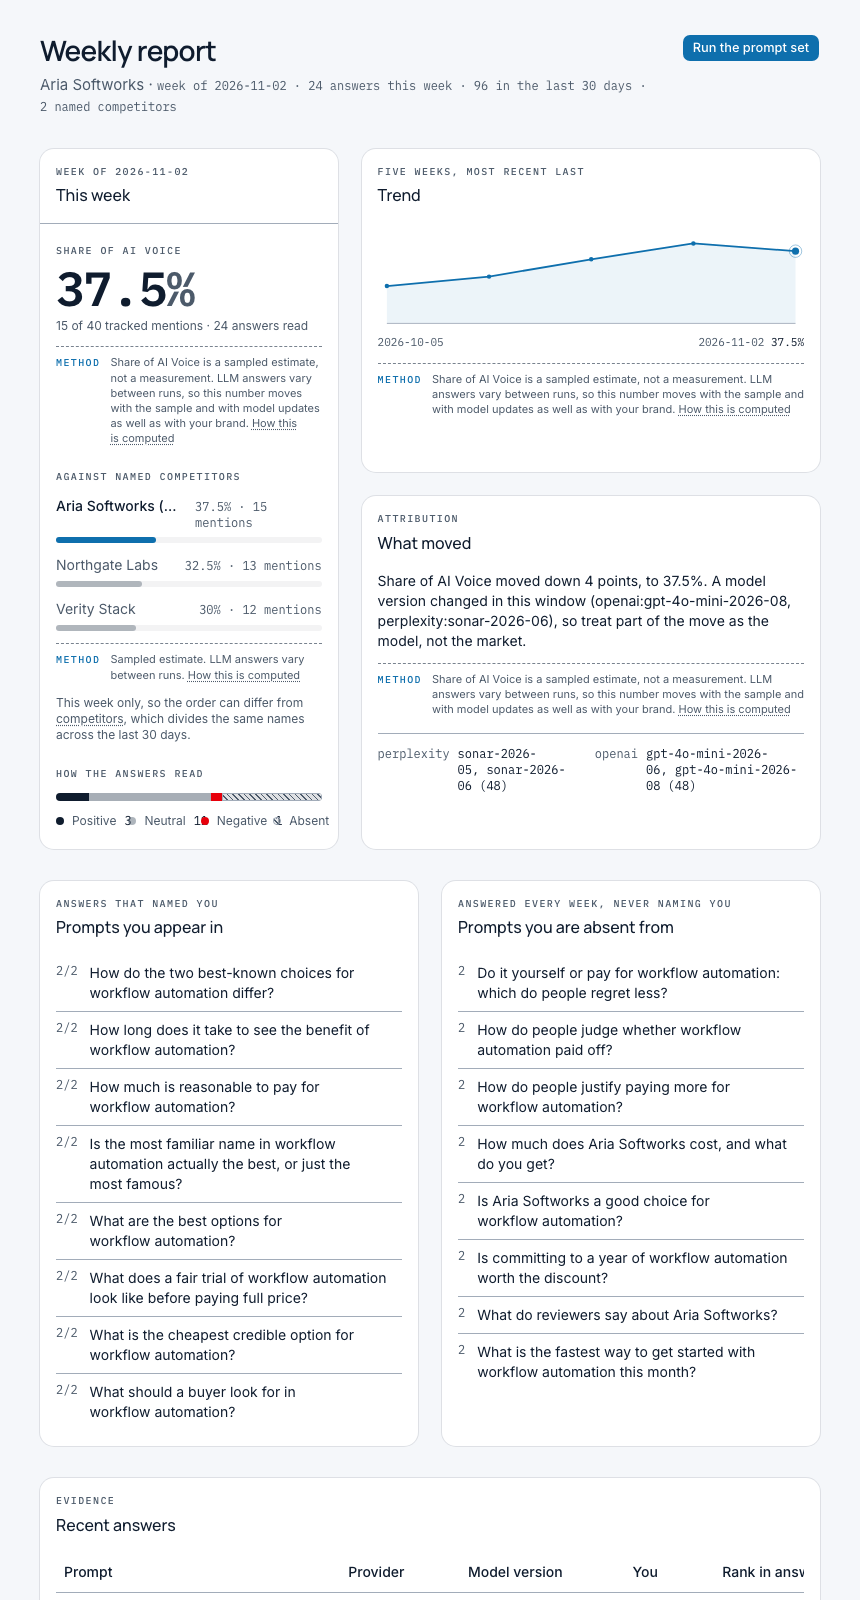
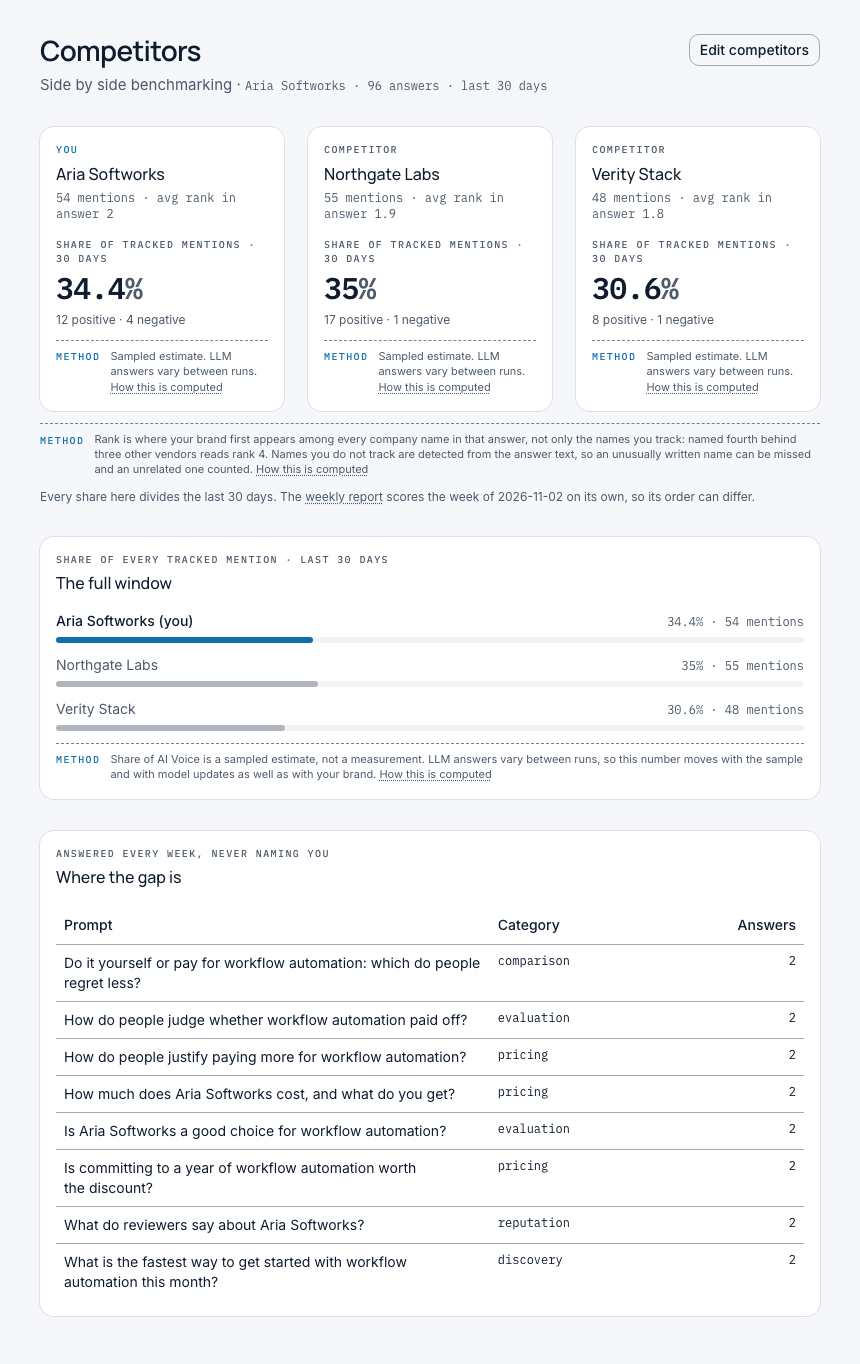
Trend lines for Share of AI Voice, the sentiment breakdown behind them, the prompts where you are named and the prompts where you are not, and a benchmarking view against the competitors you entered.
A single headline metric your CMO can hold in their head, computed per brand per week and stored with its methodology caveat text attached to the record itself, so the number and its limits never travel separately.
Every stored response carries the model version that produced it, so a shift after a provider update can be told apart from a shift in how your market actually talks about you.
How it will work
Enter your brand name, a short description, and up to three competitor names. Seenby turns that into 50 to 100 category prompt templates, with a curated fallback set if generation comes up short, and shows you the list before anything runs.
The scheduled query engine sends the prompt set to OpenAI and Perplexity through a provider adapter, isolating per-prompt failures and continuing on the remaining provider if one is unavailable.
A PII-scrubbing step runs in the storage pipeline before any response becomes queryable, and every stored response carries a scrubbed flag and the model version that produced it. Then mentions, sentiment and ranking position are extracted.
Share of AI Voice is computed once per brand per week and stored together with the methodology caveat text, so every place the number appears can show what it does and does not support.
The weekly email brings top insights and drift alerts. The dashboard holds the 30-day trend, the sentiment breakdown, the competitor comparison, and the prompts where nobody named you.
Leave an email and we will write when access opens, with the surfaces covered, the caveats that come with the score, and the price. No sequence, no drip.
One email when it launches, and one now to confirm your address. Unsubscribe any time. Privacy.