Scrunch AI vs Seenby
You are choosing between Scrunch AI and Seenby to find out how AI assistants describe and recommend your brand. This page states exactly what Seenby measures, at what price, and is equally clear about the one thing we will not do, which is characterise Scrunch AI from memory.
Seenby is not open yet, so anything on this page about what it does is what it is being built to do.
What each tool is for
Both names turn up in the same search, and for the same reason. Someone senior asked how ChatGPT describes the company, nobody had an answer, and the rank tracker the team already pays for does not measure it.
Scrunch AI sits in the AI visibility category: software for understanding how AI assistants represent a brand. That is the honest limit of what we will assert about it here, and the next block explains why.
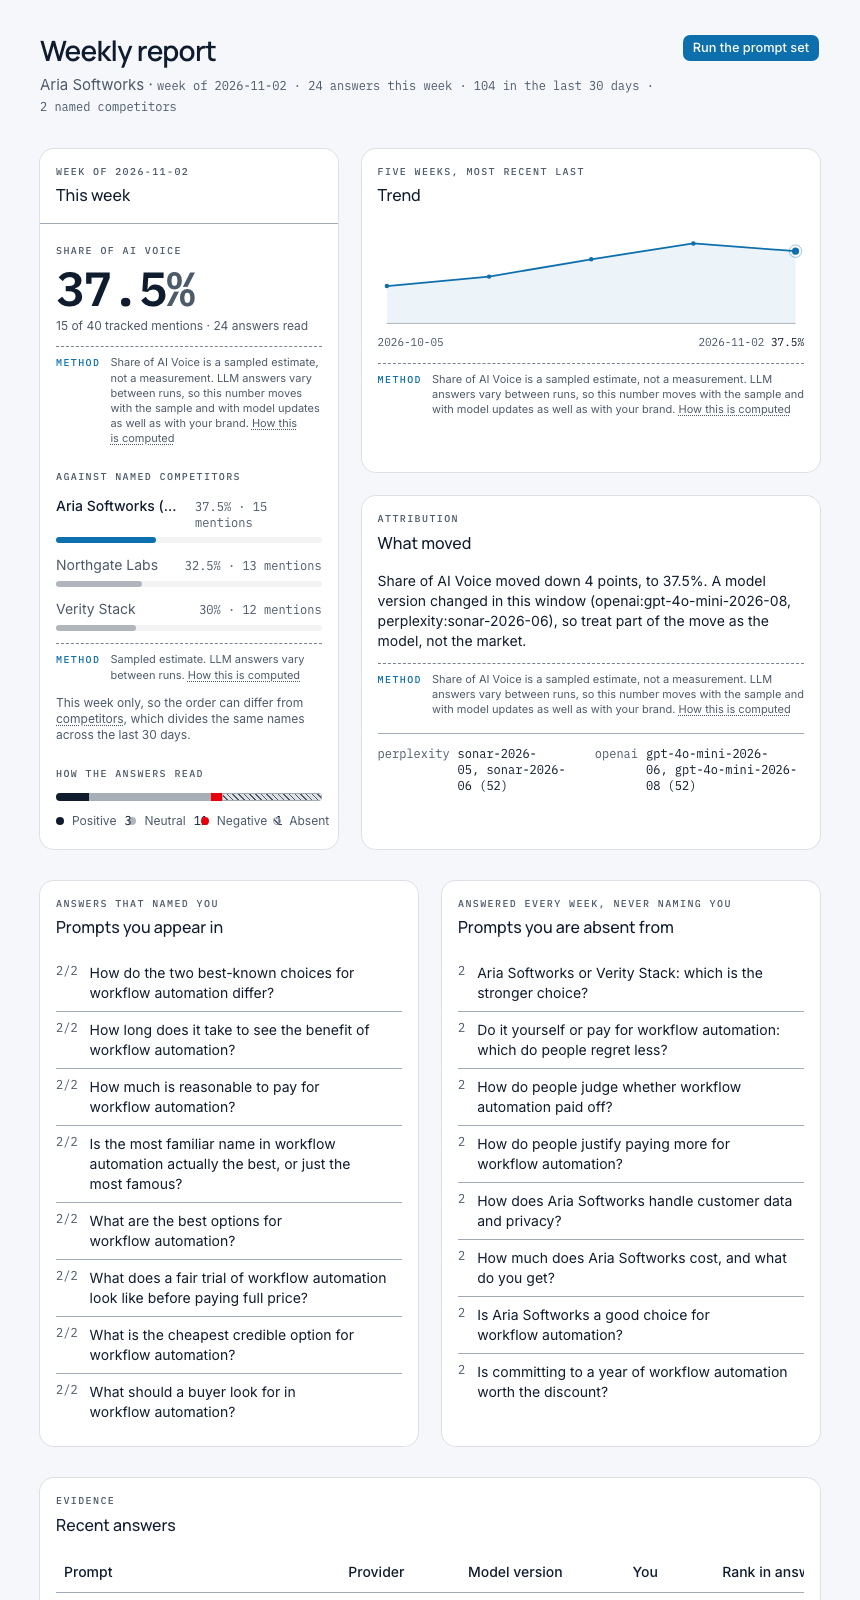
Seenby is narrower on purpose. It is built for a brand manager or SEO lead at a mid-market company who needs one defensible number, every week, for one brand, benchmarked against up to three named competitors. A scheduled query engine puts a frozen prompt set to two providers, OpenAI and Perplexity, behind an adapter interface that degrades gracefully to the remaining provider if one is disabled. A response parser pulls brand and competitor mentions out of every answer, classifies sentiment as positive, neutral, negative or absent, and records ranking position within the response. Those extractions roll up into a single headline Share of AI Voice score per brand per week, stored with its methodology caveat attached to every computed record.
Seenby is not open yet. The product is in build and the waitlist is the way in.
What we can honestly say about Scrunch AI
Very little, and we would rather say that than fill a column with plausible sentences.
We have not fetched, quoted or dated Scrunch AI's live material for this page. Everything we hold internally about their coverage, their feature set and their price is recollection, not evidence. Recollection is exactly the kind of source we built Seenby to replace, so publishing it here would be self-refuting.
So the third column below carries no capability claims, no pricing and no judgement about their reliability, security or support. Read their own site, scrunchai.com, and take their current wording over ours. Two questions are worth asking any vendor in this category, including us: which models are queried and on what schedule, and what happens to the score when the model underneath it is updated.
Side by side
| Dimension | Seenby | Scrunch AI |
|---|---|---|
| Providers queried | Two at launch, OpenAI and Perplexity, behind a provider adapter that degrades gracefully if one provider is disabled | We hold no quoted, dated source. Check their site. |
| Headline metric | Share of AI Voice, one score per brand per week, stored with its methodology caveat attached to every record | We hold no quoted, dated source. Check their site. |
| What is read out of each answer | Brand and competitor mentions, sentiment as positive, neutral, negative or absent, and ranking position within the response | We hold no quoted, dated source. Check their site. |
| Competitor benchmarking | Up to 3 named competitors, scored from the same prompt set as your brand, answer by answer | We hold no quoted, dated source. Check their site. |
| Prompt set | 50 to 100 prompts generated at onboarding from your brand name, description and competitor names, then frozen and rerun each week | We hold no quoted, dated source. Check their site. |
| Model-update drift | Every stored response is tagged with its model version, so a model update can be told apart from a real competitive move | We hold no quoted, dated source. Check their site. |
| Methodology disclosure | Surfaced in-product on every score display and on a dedicated static methodology page | We hold no quoted, dated source. Check their site. |
| Delivery | Dashboard with 30-day trend lines, sentiment breakdown and top prompts, plus a weekly email digest with drift alerts and the caveat | We hold no quoted, dated source. Check their site. |
| Brands per subscription | One | We hold no quoted, dated source. Check their site. |
| Sign-in and payment | Email and password. Card payments through Stripe, card details never reach our servers | We hold no quoted, dated source. Check their site. |
| Stored answers and personal data | Answers stored as evidence, tagged with model version, with emails, phone numbers, handles and personal names redacted before storage. Hosted on AWS in a single region. No SOC 2 or ISO 27001, no SAML | We hold no quoted, dated source. Check their site. |
How Seenby produces the number
The same questions every week
Onboarding takes your brand name, a description and up to three competitor names, and generates 50 to 100 prompt templates. The set is then frozen. If the questions changed week to week, the trend would measure the questions, not the market.
Two providers, read on a schedule
The query engine hits OpenAI and Perplexity. The adapter interface means that if one provider is disabled, the run continues on the other rather than failing entirely. Two is the honest count at launch, not a rounded-up number.
Evidence before score
Each answer is parsed for brand and competitor mentions, sentiment across positive, neutral, negative and absent, and where you rank inside the response. The score is a rollup of those extractions, so every point on the trend line has answers behind it.
One metric, with its caveat bolted on
Share of AI Voice is computed once per brand per week and stored with its methodology caveat text attached to every record. The caveat travels with the number into the dashboard and into the weekly digest, because a score without its limits is a liability.
Drift you can attribute
Every stored response carries its model version. When a provider ships an update mid-quarter, you can see whether the line moved because the market moved or because the model did, and say which in the board deck.
When to choose which
This is a shape decision more than a feature decision.
Seenby fits when
You have one brand to defend and up to three competitors you can name without a workshop. You need something scannable each Monday that a non-specialist executive can read, with the reason a number moved next to the number. You care more about a defensible weekly trend on two providers than a thin reading across many.
Look elsewhere, including at Scrunch AI, when
Your requirements list includes things Seenby does not have today, and we would rather you find that out here than three weeks into a trial. Seenby tracks two providers, not four or more. It covers one brand per subscription, so a portfolio or a client roster means one subscription each, which we cover on the agencies page. Sign-in is email and password, with no SAML or OIDC. There is no completed independent security audit, no SOC 2 and no ISO 27001, no signed data processing agreement on request, no choice of hosting region, and no self-serve export of your stored answers and scores. If procurement will stop on any of those lines, a larger platform is the more sensible evaluation, and you should assess Scrunch AI and the rest of the category against that same list using their own current material rather than ours.
If you are still deciding what to measure
A fair test of any tool in this category is to write down the five prompts your buyer actually types, then ask each vendor to show you the raw answers behind the score, not just the score. Ask how often the prompt set changes. Ask what happens to the trend when a model is updated. Those three answers separate measurement from decoration faster than any feature grid.
Questions
Does Seenby track Claude or Gemini?
No. At launch the query engine hits exactly two providers, OpenAI and Perplexity, through a provider adapter interface. If one provider is disabled the run degrades gracefully to the other rather than failing.
How much does Scrunch AI cost compared with Seenby?
We do not publish a Scrunch AI figure because we have not fetched and quoted their live pricing, and a number from memory is worth nothing to you. Their site is the source.
Can I track more than one brand on one subscription?
No. The plan covers one brand and up to three named competitors, with 50 to 100 prompts a week. Agencies running several clients need a subscription per client brand, which the agencies page explains.
Why would my score move if nothing about my marketing changed?
Because the models underneath it change. Every stored response is tagged with its model version and the weekly digest flags drift tied to model-version changes when applicable, so you can distinguish a model update from a real competitive move. The methodology caveat sits on every score display and on a dedicated methodology page.
What does Seenby store, and what happens to personal names in answers?
Your account details, the brand and competitor names you enter, the frozen prompt set, every answer the providers return with its model version, the extracted mentions and the weekly score, plus your Stripe customer id and subscription status. Emails, phone numbers, handles and personal names are redacted before any answer is stored.
Can I export my answers and scores?
Not today. Self-serve export is not in place, and neither is single sign-on, a choice of hosting region, a signed data processing agreement on request, or an independent security certification. You can delete the account and everything under it yourself from Brand settings.
Is Seenby available to buy now?
Not yet. The product is in build and the site is a waitlist. The price, the limits and the capabilities described here are what it is being built to do, not a track record.
Sources
Related
- How to choose an AI visibility tool: eleven questions to ask a vendor
A buyer's guide to AI visibility tools, built around eleven questions about model coverage, prompt sets, score method, drift, evidence, data handling and price.
- AthenaHQ vs Seenby
A comparison for anyone choosing between AthenaHQ and Seenby: what Seenby is built to do, stated from its own build, and the questions to put to AthenaHQ directly rather than take from us.
- Evertune vs Seenby
A head-to-head for anyone shortlisting Evertune and Seenby: what Seenby measures, what it will cost, what it does not have, why it is still a waitlist, and why the Evertune column on this page says ask Evertune.
- Free AI visibility checkers: what a one-off scan can and cannot tell you
A free AI visibility checker gives you one sample of how an AI model describes your brand.
- How much does AI brand monitoring cost?
AI brand monitoring is priced on query volume, so cost tracks how many prompts, providers and brands you watch.
- Otterly.AI vs Seenby
A head-to-head for brand and SEO leads choosing an AI visibility tracker: what Seenby measures, what it will cost, what it does not do, and the questions to put to Otterly.AI before you decide.